Wdata Timeout
Hello - I have noticed that occasionally in our environment, Wdata queries will timeout. It looks to be a 10-minute timeout process, and when it happens, it occurs for all chains / scripts / etc. that are running Wdata at that time. Is this a platform-wide load timeout, or is there something specific to our environment that could be causing this?
The issue is not too bothersome, as the vast majority of the time the chain / script / etc. succeeds on the next run. Just looking for some clarity so I can provide an explanation to our team for why this happens ever so often.
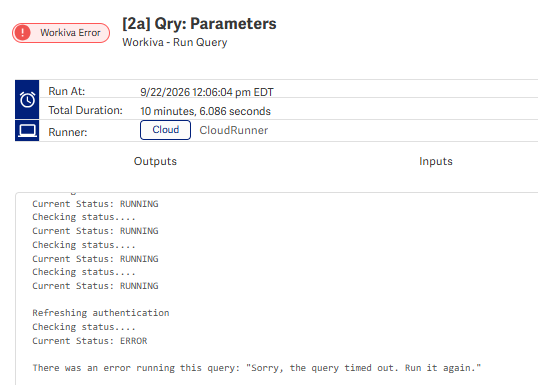
-
 Hey Joe Rufolo — happy to provide some clarity on this.The 10-minute timeout is a platform-wide limit enforced by the Workiva API — it is not specific to your environment. The Wdata API limits the length of any request to 10 minutes. This applies across chains, scripts, and any other mechanism running Wdata queries.The 10-minute timeout cannot be extended — it is a hard platform limit.Hope this is a little bit helpful for you!More details can be found here on our Support Site: Wdata Feature and API Limits0

Hi Brooke,
Thank you for the quick response! In addition, I was curious why this happens / if Wdata capacity is platform wide. These queries usually only take 5-20 seconds to run, so just curious if you have any insight into this. Thanks!
0
Hi Brooke Mortvedt - I had an additional question related to the Wdata query function.
I understand that queries cannot run for more than 10 minutes, but I am curious if you have any insight as to why occasional runs will last the 10 minutes. I notice that when my above error happens, a query which normally takes 5-10 seconds runs for the full 10 - it appears to be some sort of platform delay. I have see a query run for seemingly too long within Wdata when run manually; when I see a query taking more than 20 seconds, I will manually cancel it and restart the run - it then executes in the 5-10 seconds as normal. Do you hear similar issues from other customers? Thanks!
0
Hi Joe Rufolo - Wdata capacity and throttling is platform-wide. When the platform experiences higher-than-normal load, shorter running queries can occasionally be caught in the slowdown — which explains why everything resolves on the next retry. A tip to minimize this happening for you would be to stagger scheduled chains/scripts so that they don't all fire at the same time. If you do notice a pattern where timeouts spike at a particular time, it may be worth checking out status.workiva.com for any active platform related events!
0
Got it - that is helpful context, and I will look into our task scheduling. Thank you! Brooke Mortvedt
0Zaloguj się, aby dodać komentarz.
Komentarze
Komentarze: 5